
We benchmarked Claude Haiku 5.5 on SRE Bench. It solved our hardest multi-hop incidents, posted the fastest Anthropic investigations we have measured, and then missed the easiest task on the bo...
Blog about SRE, DevOps, Linux and Networks
We benchmarked Claude Haiku 5.5 on SRE Bench. It solved our hardest multi-hop incidents, posted the fastest Anthropic investigations we have measured, and then missed the easiest task on the bo...

Eleven of the 23 models on SRE Bench now hold a perfect root-cause score. Two months ago that club had five members. This is what benchmark saturation looks like from the inside, and it changes...
Kubernetes v1.37 is expected to add better machine-readable storage health signals. For SRE teams, that means fewer blind spots when CSI volumes degrade, mounts hang, or node storage starts failing quietly.
OpenCost 1.121.0 adds AI inference cost tracking for Kubernetes platforms running vLLM and llm-d. For SRE teams, that turns GPU spend into per-model, per-token evidence.
Prometheus v3.13.2 fixes a PromQL SIGBUS crash path that could appear when the data disk is full. For SRE teams, the lesson is simple: your monitoring system needs the same disk-failure discipline as the services it watches.
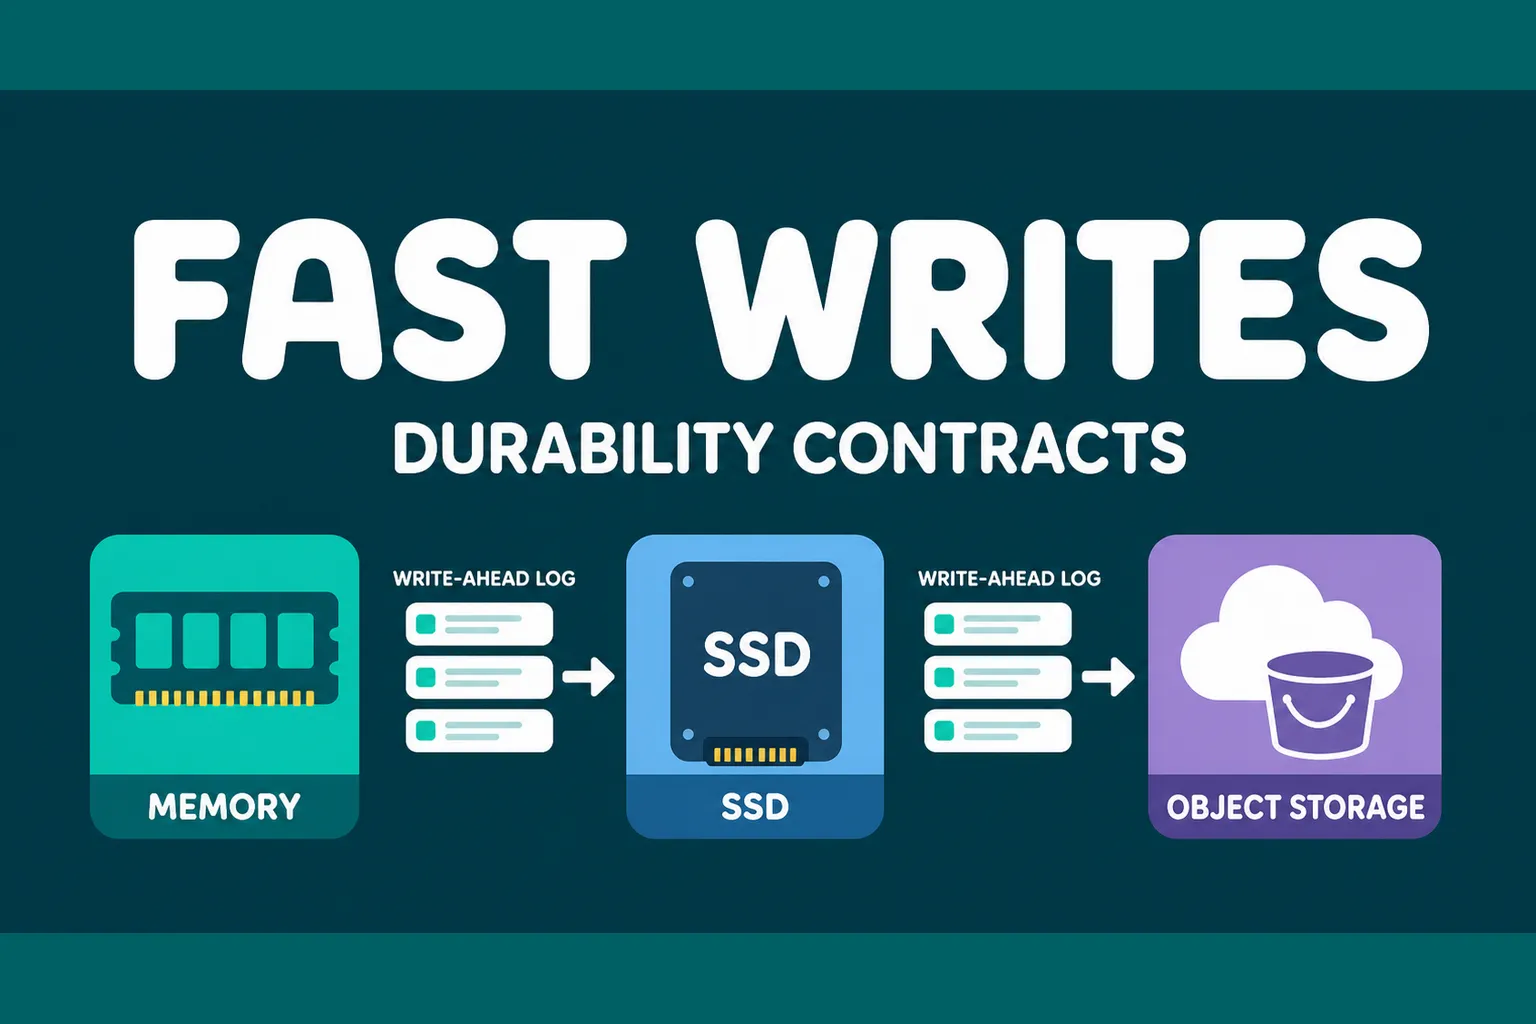
Fast write paths are safe only when everyone knows what success means. For SRE teams, the real question is which system owns durability, retry ambiguity, cleanup, and backpressure after the client gets an OK.