Self-Hosted AI Incident Response for SRE, Platform, and DevOps Teams

Akmatori takes an alert from your monitoring, investigates it on your real servers, Kubernetes clusters, and dashboards, and tells you the root cause and the fix. It runs in your own infrastructure with the LLM you choose, and production changes wait for your approval.

Open-source Apache 2.0Deploy with Docker Compose or HelmWorks with your existing alerts and runbooks

Apache 2.0 and self-hosted. Clone it, run it on your own alerts, and keep every incident, runbook, and model inside your infrastructure.

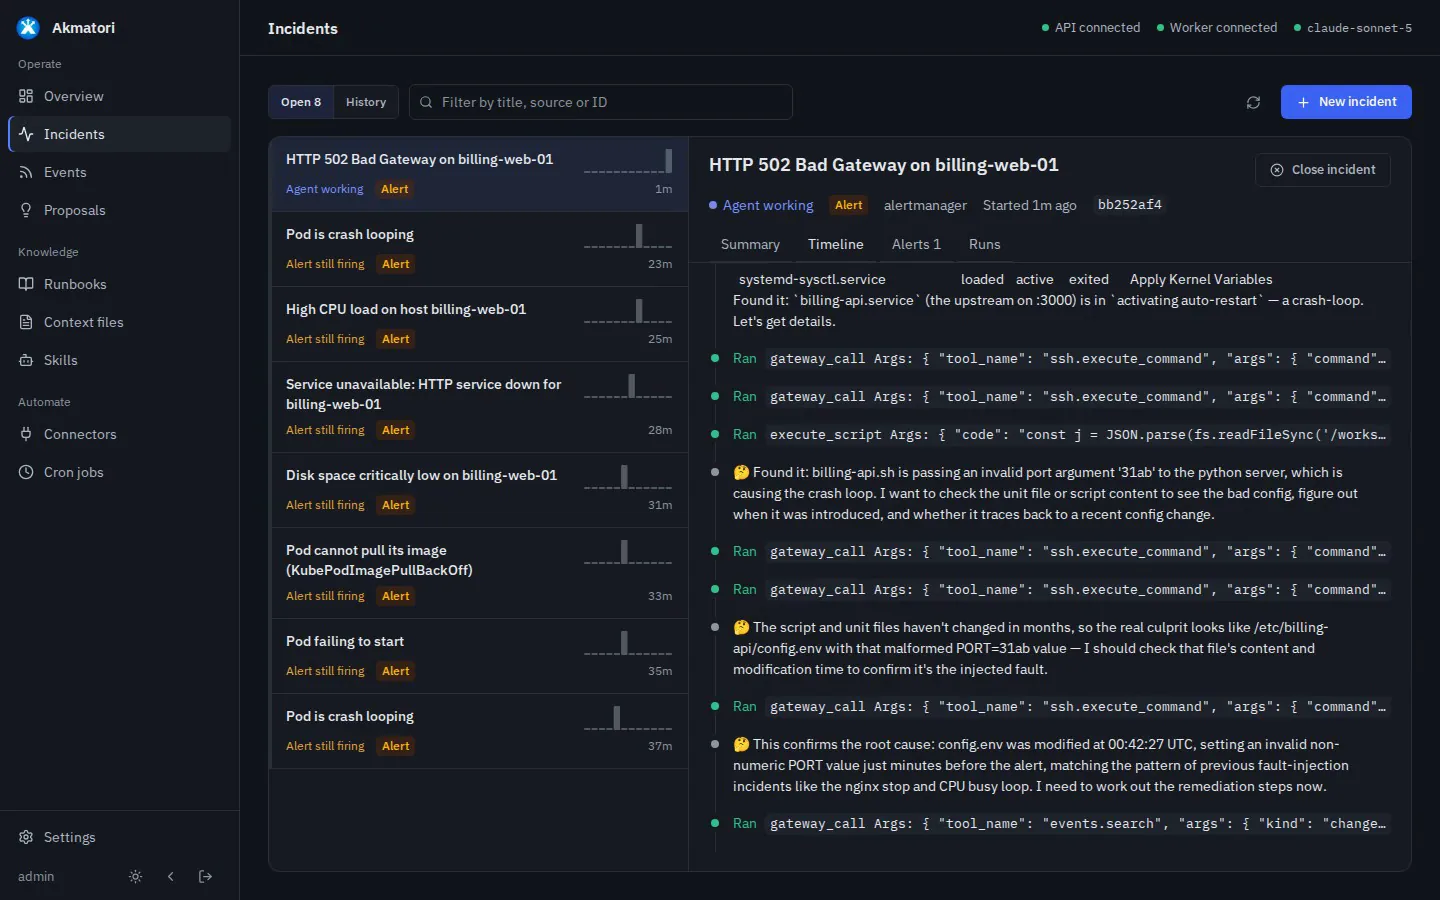
A product tour, then a real HTTP 502 incident on a Linux server, investigated live. Alert to root cause in 2 min 26 s, with read-only SSH access.

See it work on a real incident

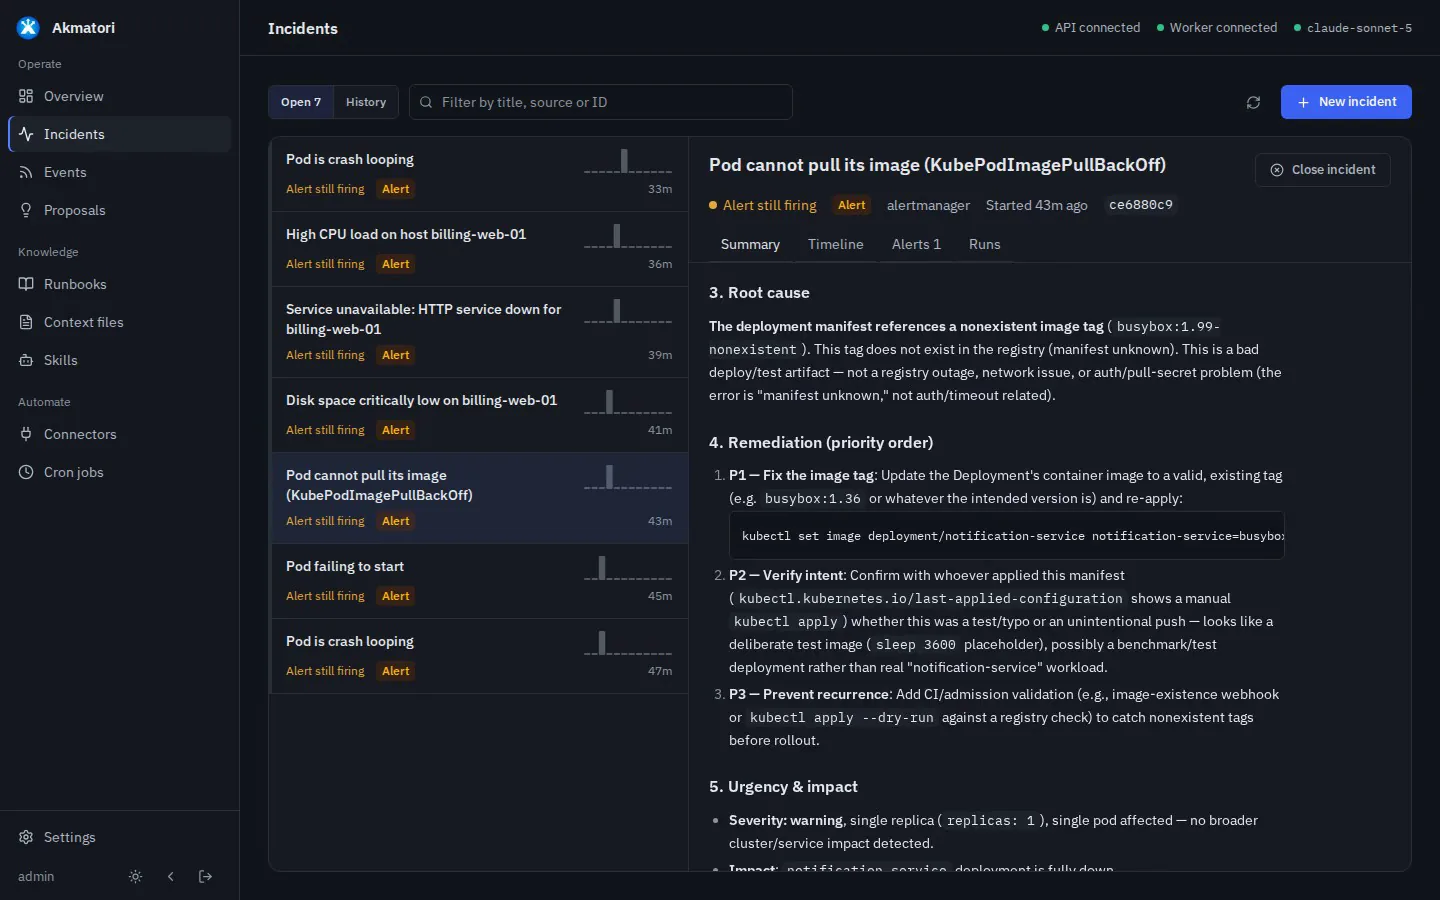
These screens come from our SRE Bench lab, where we break real servers and Kubernetes workloads on purpose and let the agent find out why.

A root cause you can act on

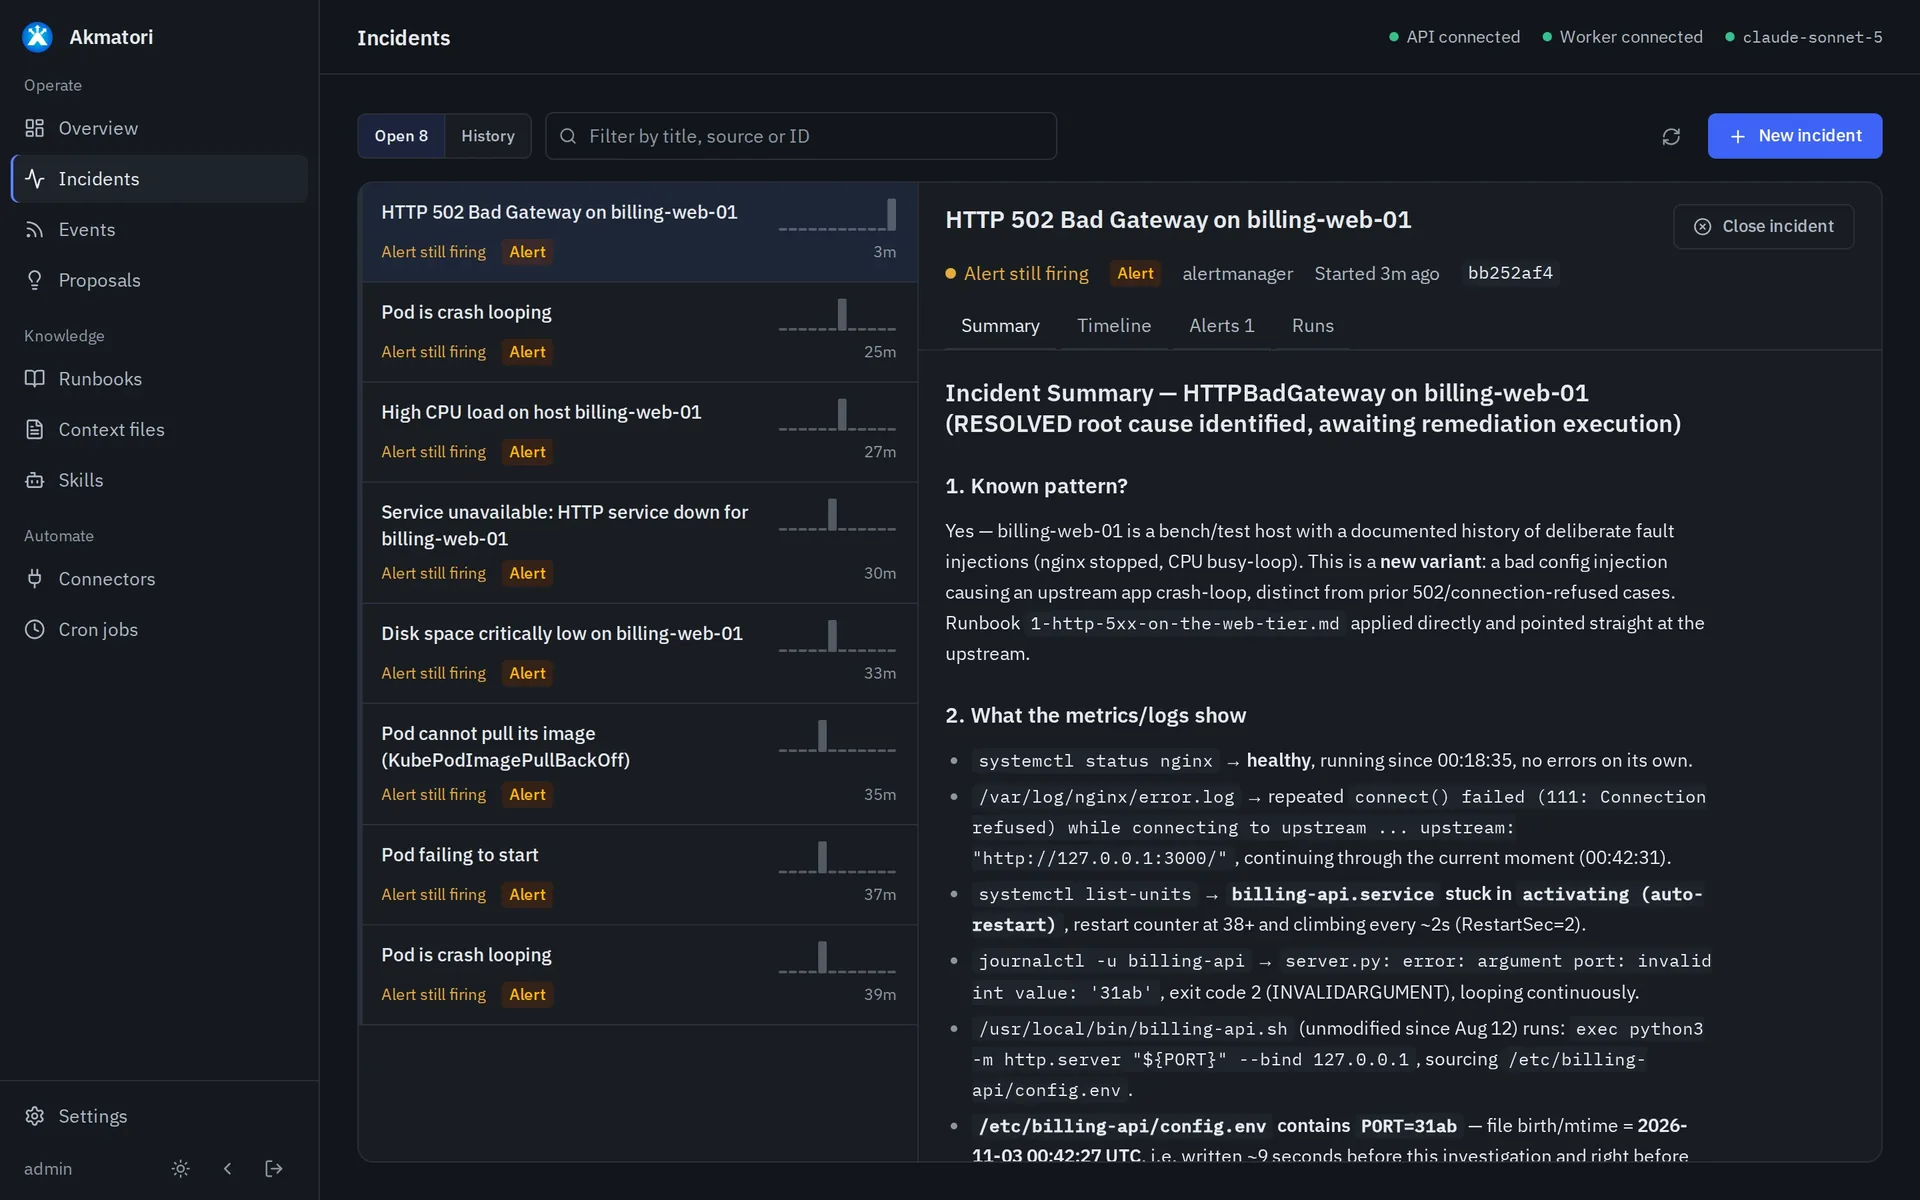
nginx returns 502 Bad Gateway. The agent finds the real cause one layer down: the billing-api config says PORT=31ab, so the service crash-loops. The summary gives the evidence, the exact fix, the checks to confirm it, and a warning not to restart nginx.

Akmatori incident summary: root cause of an HTTP 502 alert, with evidence and the fix

Get Started in 60 Seconds

Deploy Akmatori locally, install it on Kubernetes, or trigger your first AI investigation from the CLI. No vendor lock-in, full data control.

# Clone and start Akmatori in under a minute
git clone https://github.com/akmatori/akmatori.git
cd akmatori
docker compose up -d

# Open http://localhost:8080 to access the UI
Quick start guide

Best for local evaluation and fast team demos

  • Boot the full stack on localhost with Docker Compose.
  • Open the UI immediately and connect your first alert source.
  • Validate incident workflows before touching production.
Prerequisites
Docker EngineDocker ComposeGit access
You are ready when
  • The web UI loads on localhost.
  • Core services show healthy in Docker Compose.
  • You can create a test incident from the dashboard.
Verify the stack is healthy
docker compose ps

You should see the Akmatori services in a running or healthy state before opening the UI.

Developer-First

REST API Examples for SRE Tooling

Create incidents, read investigation state, download the OpenAPI schema, and route alerts from the tools your responders already use.

# Trigger an AI-powered incident investigation
curl -X POST https://akmatori.example.com/api/incidents \
  -H "Authorization: Bearer $AKMATORI_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "task": "Investigate sustained CPU saturation on prod-web-01 and summarize likely root cause",
    "context": {
      "host": "prod-web-01",
      "severity": "critical",
      "source": "prometheus",
      "metric": "cpu_usage",
      "value": 98.5
    }
  }'

# Response: Akmatori starts investigating immediately
# {
#   "id": "inc_abc123",
#   "status": "investigating",
#   "agent": "sre-agent-01"
# }
Copyable cURL
Health Checks
JWT & API Key Auth
OpenAPI 3.0 Spec
Alert Webhooks
Slack Handoff
View Full API Reference
Skip to main content

AI incident response your SREs can operate

Akmatori turns a production alert into a finished first investigation: it reads your runbooks and memory, checks recent changes, runs diagnostic commands on your systems, and writes the root cause and the fix. Risky actions become proposals that an engineer approves. Self-host it, connect the tools you already use, and test it on your own alerts.

What Akmatori Does

The capabilities that ship in the open-source platform today

Multi-Source Alert Ingestion

Ingest webhooks from Alertmanager, PagerDuty, Grafana, Datadog, and Zabbix, plus Slack channel monitoring. Keep the monitoring you already have.

Agentic Investigation

Every incident runs a full agent session. It searches your runbooks and past incidents first, then collects logs, metrics, and state from your systems until it finds the root cause.

Connectors, Not Just Chat

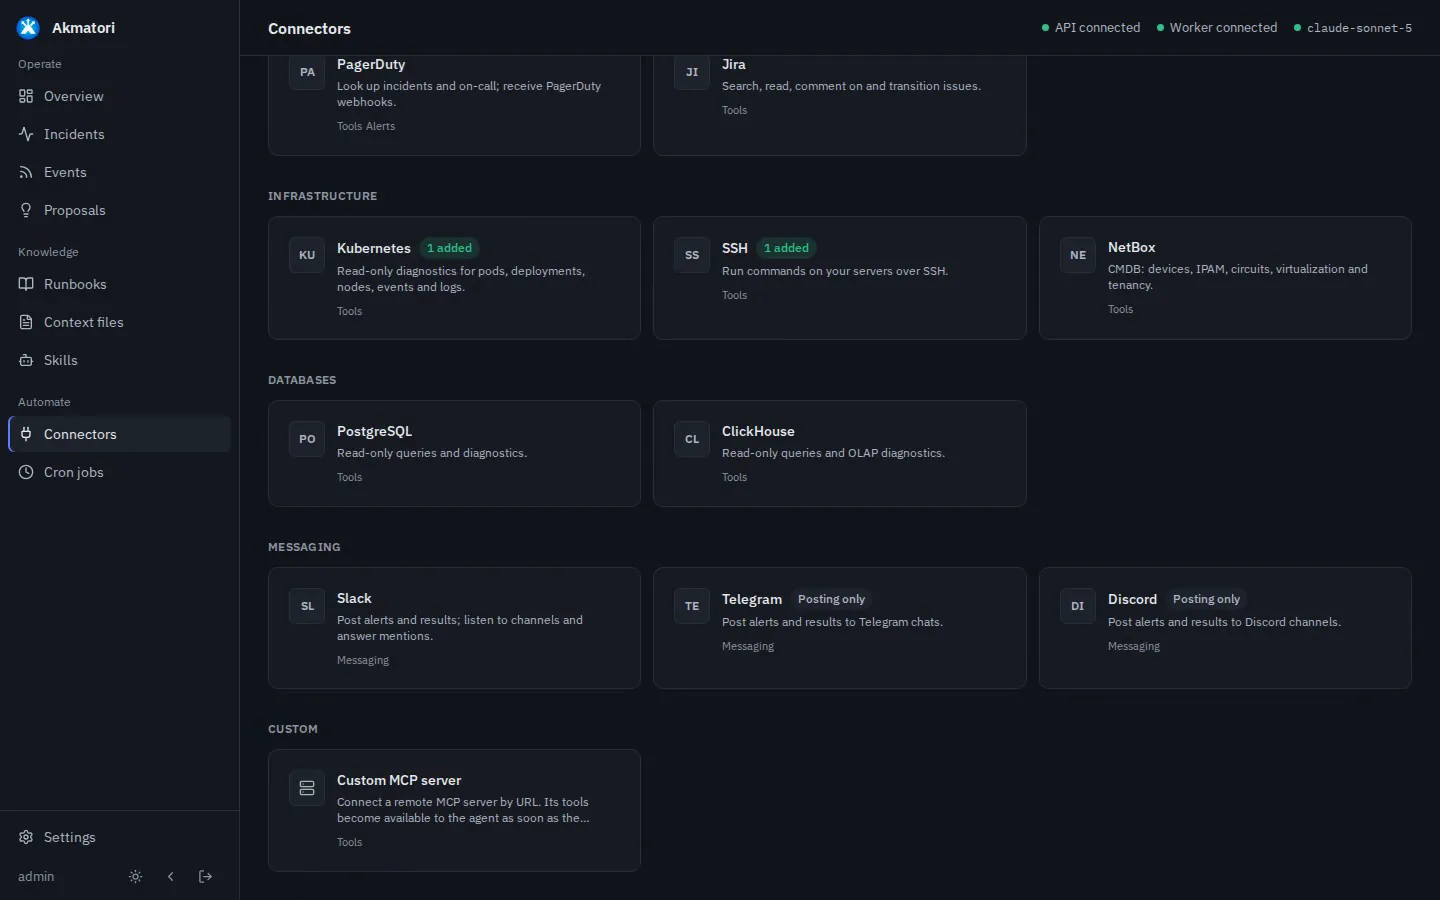
Connect SSH, Kubernetes, monitoring, databases, ticketing, and remote MCP servers once. Tools run in a separate gateway, so the agent never sees your credentials.

Approval-Gated Remediation

Risky actions become proposals you approve in the web UI or Slack before anything executes. You decide how much autonomy each agent gets.

Bring Any LLM

OpenAI, Anthropic, Google, OpenRouter, NVIDIA NIM, MiniMax, or any OpenAI-compatible on-prem endpoint (GLM, Kimi, Mistral, LLaMA). Swap providers anytime — no lock-in.

Runbooks and Memory

Your team writes runbooks. After each incident, the agent saves what it learned to memory, which you can review, edit, or delete. Skills use the open Agent Skills format.

Self-Hosted by Design

Deploy with Docker Compose or Helm. Your incident data never leaves your infrastructure — run fully on-prem with local models for air-gapped setups.

Web Dashboard + Slack

Follow every investigation step by step in the web UI, run scheduled investigations with cron jobs, and get results in Slack, Telegram, or Discord.